knowledge hub:
resources & insights
Get the knowledge and tools you need to improve contact centre performance, deliver better customer experiences and grow your business.
the latest
downloads
The 2026 UK Contact Centre Conduct Risk Report
Independent research with 285 FCA-regulated UK contact centre managers and directors. Covers detection, commercial pressure, cost, and time-to-consequence - with five questions for your next Consumer Duty board report.
85.6% are confident they could evidence fair treatment under Consumer Duty if the FCA reviewed them tomorrow.
54.0% have found a compliance breach or harm issue outside their routine QA sample. For 16.5%, it has happened more than once.
31.2% paid £50,000 or more in regulatory fines in the last twelve months.
3.08 days is the average time between a call and the agent getting feedback on it. Only 10.9% manage it inside a day.
77.5% agree that pushing sales or collections performance increases compliance risk — and it's the leaders setting those targets telling us so.
Confidence is high. Detection is patchy. The gap between them is already on the balance sheet.

The Assisted Agent Playbook
A practical guide to AI-enabled agent assistance for contact centre leaders. Covers the before, during, and after of every call - with the ROI case, a real-world scenario, and three actions you can take this week.
- 42% of UK consumers have already switched provider due to poor contact centre experience - Voice of the UK Consumer 2026
- 69% rate AI worse than humans for understanding their issue - the gap isn't the technology, it's the context being lost between calls
- £175,000 - illustrative annual saving potential for a 50-agent team from a 50% reduction in wrap time alone, without reducing headcount
- 50% wrap time reduction - what Agent Wrap Up Summary delivers, returning hours of capacity back to productive contact time every shift
- 100% call coverage - from QA sampling to full-call insight, without adding resource
The Voice of the UK Consumer 2026: The Trust Gap
UK consumers are screening calls, ignoring messages, and filtering out legitimate contact because they can no longer tell what's real. MaxContact's 2026 Voice of the Consumer report covers how businesses can adapt.
Over two thirds of UK consumers always or often screen calls from numbers they don't recognise. Half have ignored a message from a legitimate company because they assumed it was a scam or fraud. This isn't a fringe behaviour — it's the default. And it means legitimate contact centres are losing customers before a single conversation starts.
When consumers screen out genuine contact, the consequences are real:
- 37% had to contact the company later to resolve a problem that got worse
- 31% missed important service information
- 21% missed an appointment or a payment deadline.
the latest
webinars and events

Build High Performing Outbound Teams
The average contact centre takes 3.08 days to get feedback back to an agent after a call. By the time it lands, that agent has already had another day or two of calls to repeat whatever needed fixing. That gap is costing you deals, not just compliance evidence.
Let Compliance Sleep: See what full coverage QA looks like
New PECR penalties. Active FCA enforcement. Directors personally on the hook. Automated QA is no longer a "nice to have".

The Consumer Trust Gap: Why Your Calls Aren't Getting Through
69% of your customers screen unknown calls. Here's how to earn the answer anyway.
the latest
videos
AI Agents - Inbound Customer Service
Say hello to MaxContact’s AI Customer Service Agent: a digital team member that answers in seconds, resolves issues instantly, and hands over to humans when empathy is needed.
AI Agents - Outbound Sales
Meet MaxContact’s AI Sales Agent—your always-on, always-consistent team member that instantly reconnects with old leads, qualifies new ones, and books meetings while your reps focus on closing.
AI Agent - Payment & Collections
Meet MaxContact’s AI Payment & Collections Agent: a compliant, always-on team member that drives more payments without adding more people.
the latest
client stories
AI-powered conversation analytics for Honey Group
We spoke to call centre manager Karl Burke to learn more about how Conversation Analytics by MaxContact has been the right partner for the next level of The Honey Group’s evolution.
Who:
- Honey Group, an estate planning and legal services company
- Contact centre with 40+ staff
- Booking appointments for 90+ active sales consultants
What:
- Needed to improve call outcomes, agent performance, and compliance monitoring
- Wanted to review all calls without the need to dramatically increase the size of the Quality Control team
- Wanted to enhance call success conversion rates and provide better insights for training and development
Outcome:
- Implemented Conversation Analytics by MaxContact for speech analytics and call transcription
- Gained valuable insights into agent performance and call topics
- Improved ability to identify training needs and optimise call centre operations
- Gained ability to review 100% of conversations automatically
How ICX Streamlined QA Processes with Conversation Analytics
ICX has transformed its approach to quality monitoring and compliance with MaxContact’s Speech Analytics solution.
ICX, a prominent player in the automotive industry, has transformed its approach to quality monitoring and compliance with MaxContact’s Speech Analytics solution. Within months of implementation, the team has achieved significant efficiency gains while improving their ability to monitor compliance at scale. The solution has enabled ICX to move away from fully manual, time-intensive call reviews. Conversation Analytics intelligently identifying calls that are more likely to require attention - allowing quality assessors to prioritise reviews and focus on strategic improvements instead of sifting through every interaction.
Protector Insurance: Better Visibility, Stronger Performance
Find out how Protector Insurance used MaxContact to improve reporting, monitoring and service levels — achieving 99% of calls answered within 20 seconds.
Protector is a growing insurance organisation operating across three core lines: liability, property, and motor fleet. With more than 200 UK-based employees and continued monthly onboarding, the business is expanding steadily across the UK and Europe, with offices in Manchester, London, Birmingham, the Nordic countries, and Paris.
Its UK phone operations is centred around claims handling teams based primarily in Manchester, where the teams manage large volumes of inbound and outbound calls each day. Team leaders support claim handlers through coaching, performance management, and service level oversight.
As the business grew, Protector needed a customer engagement solution that offered greater flexibility, stronger reporting, and more usable functionality than its previous provider. MaxContact now supports that operation with improved data access, real-time dashboards, and emerging AI adoption that are helping shape the next stage of development.
the latest
articles and insights
13 Things a QA Scorecard Can Tell You Beyond Pass/Fail
Scorecards do more than compliance QA. Here are 13 ways to use one, from predicting churn to meeting FCA Consumer Duty to building your AI automation roadmap, plus how to set each one up in MaxContact.
Scorecards do more than quality assurance. The same mechanic, built as a rating, pass/fail, or observation question, can predict customer outcomes, meet UK regulatory requirements like FCA Consumer Duty, surface commercial opportunities, and build a data-backed case for where to introduce AI agents. This guide covers 13 ways to use one, plus how to build each use case in MaxContact.
In This Article
- How Scorecards Work
- Predicting Customer Outcomes
- Compliance and Regulatory Risk
- Commercial and Sales Performance
- Operational and Product Insights
- Getting Started
- FAQs
For years, the case for automated QA rested on one number: most contact centres only review 2-5% of their calls. That's no longer the gap. According to MaxContact's 2026 UK Conduct Risk Report, 46.7% of regulated contact centres now use AI to review every call, nearly matching the 49.5% still sampling manually. Coverage, in other words, is largely solved.
What isn't solved is what happens next. The same research found that 54% of contact centres had a compliance breach or harm issue surface outside their routine QA process, and 16.5% found more than one. Reviewing every call tells you what happened. It doesn't tell you what's about to happen. It won't flag who's about to churn, which calls should never have happened at all, or which agent needs help before their next review cycle.
That's the real opportunity in a scorecard. Not just scoring compliance after the fact, but turning every call into a signal you can act on, for coaching, for commercial performance, and for risk. Here are 13 ways to do it.
How Scorecards Work
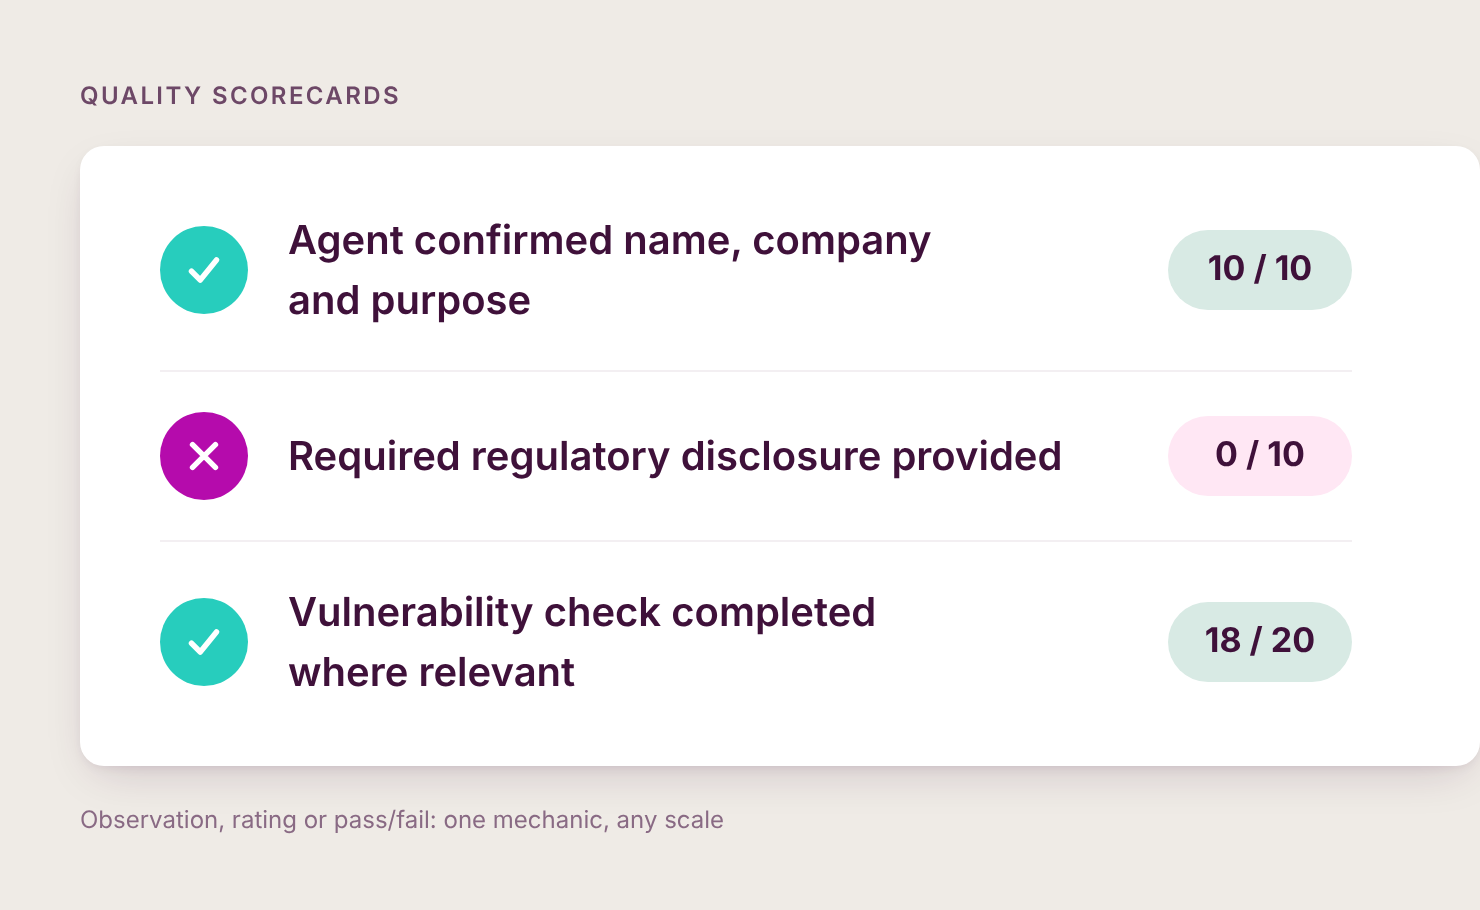
Before diving into the use cases, a quick note on mechanics. It's what makes all of this possible in MaxContact Conversation Analytics, rather than needing a different tool for every job.
A MaxContact scorecard question can be built as an observation (a few lines of AI commentary on what it found), a rating (a score on any scale you choose, such as 1 to 5, or a simple true/false), or a pass/fail. The same underlying mechanic, "based on this transcript, did X happen?", powers everything from a compliance check to a churn prediction.
Scorecards can also run two ways. An always-on schedule scores every new call as it lands, continuously. A one-time schedule runs against a historical sample instead, useful for testing a new use case against last quarter's calls before switching it on for good.
Results then roll up into question-level reporting, so you're not digging through individual calls to see which questions are failing, where, and for whom.
Predicting Customer Outcomes
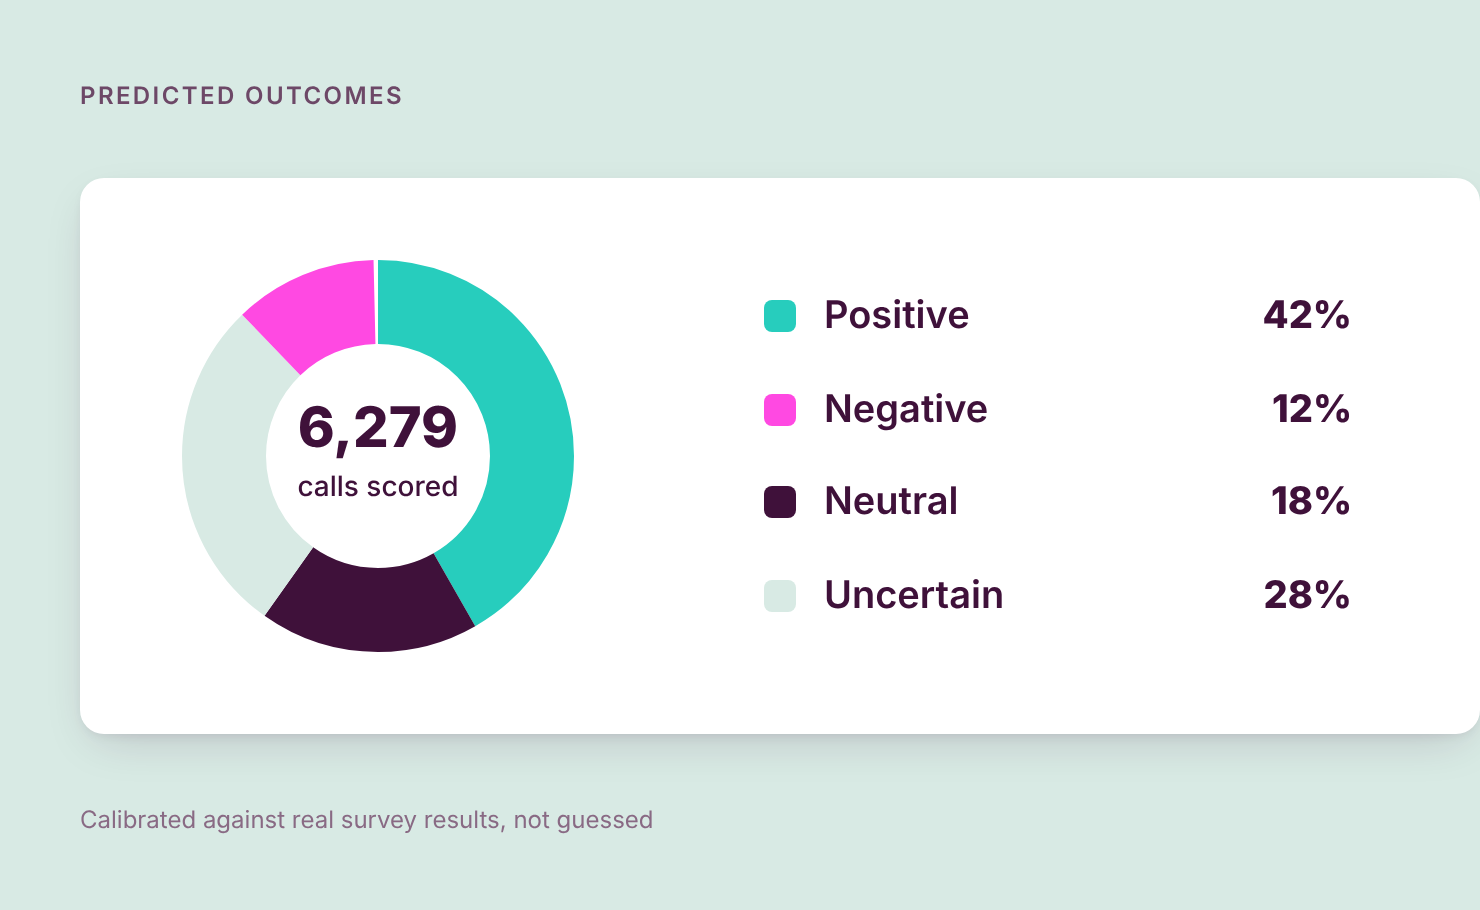
Predicted CSAT and NPS
A scorecard question can ask, in plain terms: based on this transcript, what would this customer's CSAT score likely be? Because it runs on every call, you get a sentiment read on 100% of conversations, not the 5% or so that respond to a post-call survey.
The catch: this is only credible once you calibrate it against your real survey results. Run the question alongside your existing survey data, check how closely the predictions track the real scores, and adjust until they're reliably close. Skip that step and all you've got is a sentiment score, not predicted CSAT. You have a sentiment score wearing a more exciting name. Once calibrated, the same logic extends to NPS.
Repeat Contact and FCR Likelihood
Was the issue actually resolved on this call, or is the customer about to ring back? A scorecard can score first-contact-resolution (FCR) likelihood directly from the transcript. Did the agent confirm the issue was fixed, or leave it open, vague, or dependent on another team?
This is arguably more actionable than CSAT, because failure demand has a direct, calculable cost. At roughly £5 per service call, every repeat contact doubles the cost of that interaction. That's before you've factored in agent time or the churn risk a frustrated second call brings with it.
Promise-to-Pay Likelihood
For collections teams, a scorecard can rate how firm a payment commitment was. Not just whether a promise to pay was logged, but whether the language was definite ("I'll pay Friday") or hedged ("I'll try to sort something"). The question can be scoped so it only applies when an arrangement-to-pay or promise-to-pay outcome has been set, rather than running on every call.
Because the strength of that commitment is directly tied to revenue collected, this gives collections leaders a leading indicator: a queue of weak promises worth a follow-up call, before the due date passes and it becomes a broken promise instead.
Customer Churn Intent
A scorecard question can rate whether a call shows real churn risk: cancellation language, competitor mentions, or complaints that keep repeating across contacts. Score it as a simple true/false, or as a numeric risk rating to see customers nudging from low to high risk before they act on it.
Either way, the output is the same: a retention queue built from what customers are saying, not from account age or a generic risk model.
Compliance and Regulatory Risk
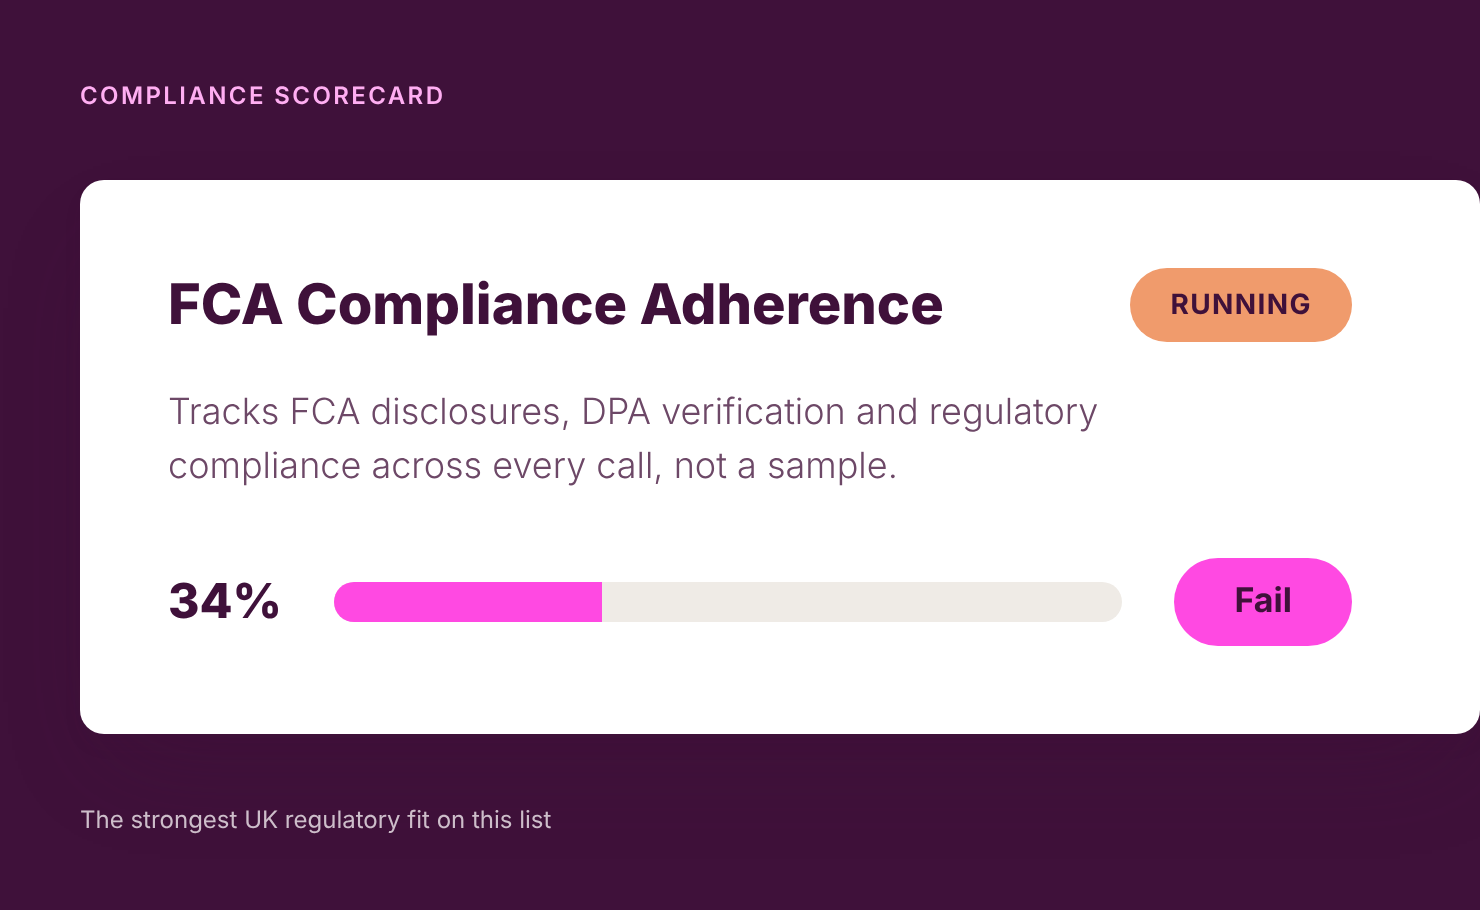
Vulnerability Detection
Under FCA (Financial Conduct Authority) Consumer Duty, firms have to identify and respond appropriately to vulnerable customers, and increasingly, prove they did. The FCA's own framework names four drivers of vulnerability: health, life events, resilience, and capability. A scorecard question can be built to listen for the language that signals each of these. It scores whether the agent picked up on it, and flags whether they fully acknowledged it, only partially addressed it, or missed it entirely.
This is the strongest UK regulatory fit on this list, for a simple reason: firms already know they struggle with it. Last year, the FCA reviewed 180 board reports and found the most common failure wasn't a lack of effort. It was an inability to evidence outcomes for vulnerable customers specifically. A scorecard that runs on every call, not a sample, is a direct answer to that evidence gap.
Complaint Detection
Under FCA rules, an expression of dissatisfaction counts as a complaint whether or not the customer ever uses the word "complaint." A scorecard can be built to catch that distinction, flagging calls where a customer expressed real dissatisfaction, even phrased as a passing comment, so they get logged and handled as complaints rather than closed out as routine queries.
This is a clear compliance win with a direct cost attached. MaxContact's 2026 UK Conduct Risk Report found the average regulatory fine paid by UK contact centres in the past 12 months was £81,000, across everyone surveyed, including businesses that paid nothing at all. Nearly a third paid £50,000 or more. Since February 2026, the stakes have risen further still. The Data Use and Access Act raised the maximum PECR (Privacy and Electronic Communications Regulations) fine from £500,000 to £17.5 million or 4% of global turnover, whichever is higher. For the first time, company directors can also be held personally liable, for up to £500,000 individually.
Fraud and Social Engineering Signals
A scorecard can be trained to listen for the patterns that indicate fraud risk on a call: pressure tactics, inconsistent answers to identity questions, or signs that a third party is coaching the caller in the background. Scored consistently across every call, a pattern that's easy to miss in a single conversation becomes visible at scale, and auditable after the fact.
Fines aren't the only cost at stake here either. The same research found non-compliant sales cost UK contact centres an average of £22,000 in lost revenue over the past year through refunds and cancellations. Just over half of respondents (50.2%) said they'd lost a sale, a contract, or a customer entirely over a compliance issue.
Commercial and Sales Performance
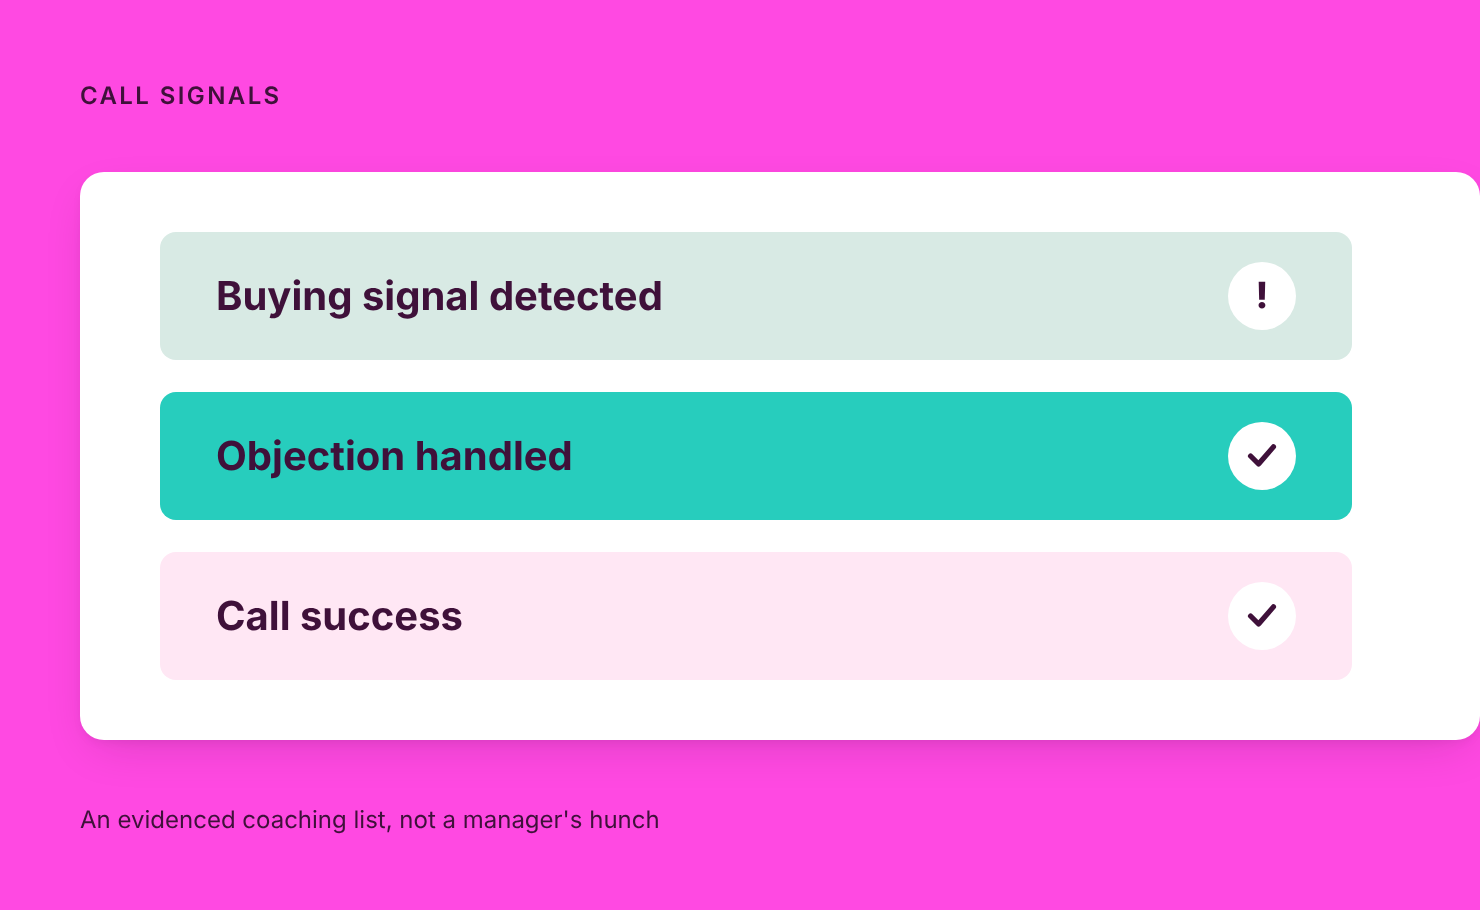
Missed Sales Opportunities
A scorecard question can flag buying signals an agent didn't act on: a customer who asked about an upgrade, mentioned a competitor's offer, or hinted at a bigger need the agent never followed up on. Run across every call, this builds a clear, evidenced coaching list, rather than a manager's hunch about who's leaving revenue on the table.
Sales Methodology Scorecards
A scorecard can also check whether an agent followed a specific sales methodology, not just whether they spotted an opportunity. A BANT scorecard, for example, scores a call against the four areas the framework is built on: Budget, Authority, Need, and Timeline. Each becomes its own rating question, usually scored on a 0-5 scale in this example (ratings can run on any range you choose), with a minimum score needed to pass (3 out of 5 was the bar in the original demo), plus an observation question at the end to pull the whole picture together.
The same approach works for any other sales methodology your teams are trained on, including FAB, AIDA, or SPIN. Because every call gets measured against the same criteria, you get a consistent read on how closely the team is actually following the methodology, not just whether revenue came in.
Script and Campaign Effectiveness
Because scorecards score consistently and at scale, they're a ready-made engine for A/B testing. Run the same scorecard against calls using different script versions or campaign approaches, and compare outcomes directly: which version holds objections better, which closes faster, which gets flagged for compliance issues less often. The scorecard becomes the measurement layer for commercial experiments you're already running, instead of a side project in a spreadsheet.
Operational and Product Insights
Automation Candidacy
This is where a scorecard stops being purely a QA tool and starts building your automation roadmap. Start with one scorecard and one pass/fail question: is this call type a good candidate for automation? Pair it with an observation question asking what, specifically, makes it one. Run it across your calls and your candidates start to emerge: complaints, vulnerability checks, simple status updates, whatever they are for your business.
From there, write a dedicated scorecard with one question per candidate type, each scored pass/fail. Run that as a one-time scorecard against a historical sample, and you get a hit rate per candidate: this type of call could have been automated 87% of the time, that one only 20%. That gives you a data-backed, evidenced pipeline for deciding what to automate first, not a guess about where AI Agents could help, but a ranked list built from your own call data.
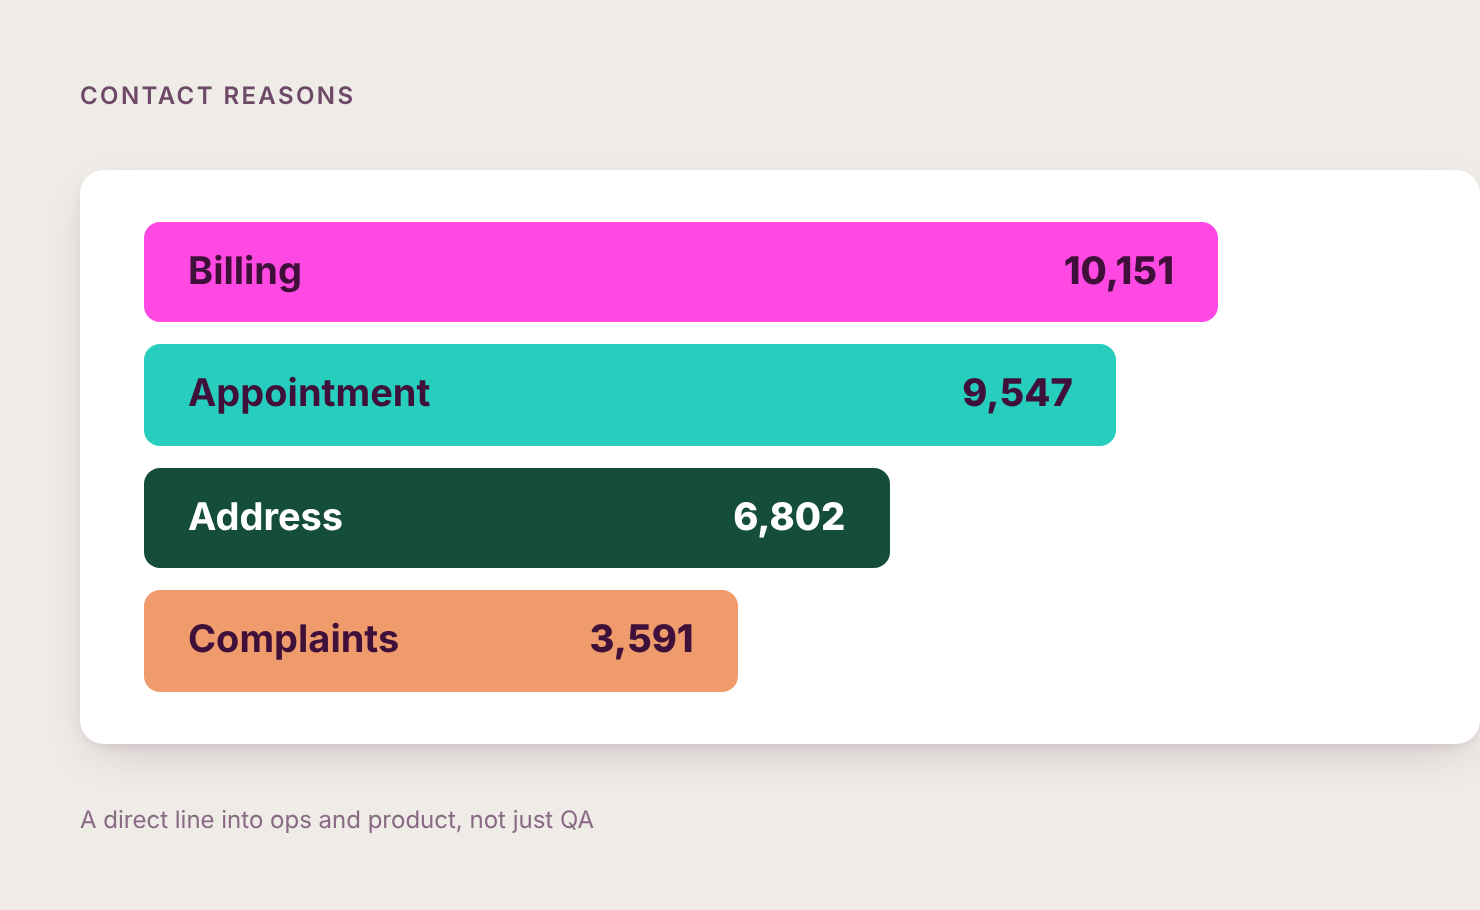
Contact Reason and Failure Demand
A scorecard can categorise why a customer called, and more usefully, flag which of those calls shouldn't have needed to happen at all. A customer chasing an order update because a text alert never arrived is failure demand: a problem created somewhere else in the business that lands on your contact centre's call volume. This is valuable well beyond QA. It's a direct line into your ops and product teams about where the underlying process is broken.
Knowledge Gaps
Agent uncertainty, excessive holds, and unnecessary transfers are all symptoms a scorecard can detect and score consistently. Rather than treating this as an individual performance issue, use it to point at the knowledge-base articles or training modules that need fixing. The same hesitation showing up across multiple agents on the same topic is a knowledge gap, not a coaching gap.
Getting Started
Here's how to turn any of these into a live scorecard in MaxContact.
1. Start with one use case, not all 13. Pick the one with the clearest payoff for your team right now. Vulnerability detection if Consumer Duty evidence is your biggest exposure, churn intent if retention is the priority.
2. Write or import the scorecard. Describe the question in plain English and let the scorecard builder turn it into evaluation criteria, or import an existing scorecard if a similar methodology already exists elsewhere in the business.
3. Choose your question type. Decide whether the use case needs an observation (a few lines of commentary), a rating (true/false, or any numeric scale, such as 1 - 5), or a straight pass/fail.
4. Scope it, if it needs scoping. Some questions only make sense in context. A promise-to-pay question, for example, should only fire when an arrangement-to-pay outcome has actually been logged on that call. Scorecards can be scoped to specific products, outcomes, or campaign types so you're not scoring irrelevant calls.
5. Test it against a historical sample first. Run it as a one-time scorecard against last month's or last quarter's calls before switching it on live. This matters most for anything predicting an outcome: CSAT, churn, automation candidacy. Check the results against what you already know before trusting it at scale.
6. Switch to an always-on schedule. Once you're confident in the results, move the scorecard to an always-on schedule so it scores every new call automatically, with no manual sampling involved.
7. Review through question-level reporting. Don't just watch an aggregate score. Use question-level reporting to see which specific questions are failing, for which agents, teams, or call types, so the next action is obvious rather than buried in an overall pass rate.
FAQs
Does this replace manual QA entirely? Not necessarily. Many regulated contact centres run scorecards alongside manual spot-checks, especially while a use case is new or being calibrated against real outcomes. What it replaces is reliance on a 2-5% sample as your only evidence base.
How accurate is predicted CSAT? It depends entirely on calibration. Run it alongside real survey data first, check how closely the predictions track actual scores, and adjust the scorecard question until they align. An uncalibrated predicted CSAT score is just a sentiment score with a different name.
Can I run a scorecard on calls that already happened? Yes. One-time scorecards can run against a historical sample, which is useful for testing a new use case or auditing a past period, rather than only scoring calls as they come in.
Do I need a different tool for each use case? No. Every use case on this list runs on the same scorecard mechanic: observation, rating, or pass/fail questions, inside Conversation Analytics. What changes is the question you ask, not the platform.
Does automation candidacy mean an AI agent takes over immediately? No. It identifies and ranks which call types are good candidates for automation based on real call data, giving you an evidenced starting point for deciding where to introduce AI Agents, rather than a guess.
Sampling isn’t evidence: what the new compliance rules mean for your contact centre
Fines are up 35x, the FCA wants proof, and most breaches are slipping through the calls nobody reviews. Here’s what the data says — and what to do about it.
Compliance used to be something you could, quietly, budget for. A fine here, a sample there, a QA process that reviewed a small slice of calls and hoped the rest looked the same.
That maths no longer works.
In 2026 the cost of getting it wrong has changed by an order of magnitude, and regulators have moved from asking whether you’ve done the work to asking you to prove it. In our recent webinar, Kayleigh Tait and Conor Bowler walked through what’s changed, shared new research from more than 300 UK contact centre leaders, and showed how MaxContact’s Auto-QA closes the gap. Here’s the summary.
The 2026 compliance landscape
Two things have shifted at once.
First, the numbers. PECR - the regulation governing outbound calls, texts and marketing communications - used to cap fines at £500,000. Since the Data (Use and Access) Act came into force in February 2026, that cap has risen to £17.5 million, or 4% of global turnover, whichever is higher. That’s a 35x increase in maximum exposure. And for the first time, company directors can be held personally liable, up to £500,000 each.
Second, the FCA’s stance. Consumer Duty has been law since 2023, but the regulator has moved from “have you put this in place?” to “prove it with evidence.” Of the 180 board reports the FCA reviewed last year, the most common failure wasn’t that firms hadn’t done the work - it was that they couldn’t evidence the outcomes for vulnerable customers.
At these levels, a fine isn’t a line item you plan for. It’s a risk you have to design out.
What the research found
To ground this in reality rather than headline numbers, MaxContact commissioned independent research across 300+ UK contact centre leaders, 285 of them FCA-regulated. A few findings stood out.
Coverage has matured - but gaps remain. Asked how they review calls today:
- 49.5% still sample manually
- 46.7% already use AI to review every call
- 2.8% review nothing systematically
That’s a more mature picture than the “2–3% sampled” figure often quoted in industry research. But it also confirms that a real share of organisations still aren’t solving the problem with technology.
Sampling leaves you exposed. More than half - 54% - said a compliance breach or harm had occurred outside their routine QA process. 16.5% said it had happened more than once. The point is simple: if you only look at a sample, the problems tend to live in the calls you didn’t look at.
And it costs real money. Across everyone surveyed - including firms that paid nothing - the average regulatory fine in the last 12 months was £81,000, with 31% paying £50,000 or more. Fines weren’t the whole story either: the average lost revenue from non-compliant sales (refunds, cancellations, deals that fell through) was £22,000, and 50.2% said they’d lost a sale, contract or customer over a compliance issue.

The confidence gap
One of the more revealing findings came from asking teams two questions. First: how confident are you that you could evidence fair treatment if the FCA came knocking? Confidence was high across the board.
Then we flipped it: have you actually found a breach outside your QA sample? The gap between the two is the interesting bit.
It’s less about how hard a team looks and more about what they’re looking at. Sales and collections calls tend to follow scripts and structured flows, so there are only so many ways a conversation can drift out of compliance. Customer care and technical support calls are far less scripted - troubleshooting, escalations, one-off advice - so there’s more variance per call, and more chance of a breach hiding in the calls that never make it into the sample.
The feedback delay problem
Even when issues are caught, they’re caught slowly. On average, it takes 3.08 days between a call happening and the person who took it getting feedback. Only 10.9% hear back within a day; over a third (37.2%) wait three days or more.
The blocker isn’t attitude. Time, cost and headcount accounted for 37.4% of the reasons given, while only 6% felt there was no genuine need for faster feedback.
That delay matters, because feedback has a shelf life. Third-party research shows employees are 3.6x more likely to say they’re motivated to do outstanding work when feedback comes daily rather than at a quarterly or annual review. Put the two together and the risk is clear: if something’s going wrong on a call and nobody flags it for the best part of a working week, it’s probably happening again and again in the meantime.
AI Call Scoring vs Auto QA at Scale
MaxContact addresses this with two features inside Conversation Analytics. They’re easy to blur together, so it’s worth being precise.
AI Call Scoring is an AI scorecard builder, included in the Conversation Analytics base package. You write the scorecard in plain English, and it scores individual calls — a human still picks which calls to run it against. It cuts review time from 2–3x the length of the call down to around five minutes per call.
Auto QA at Scale takes those same scorecards and runs them on a schedule - historically and as new calls come in - so you get consistent coverage across 100% of eligible calls. Every result is backed by evidence in the transcript, and calls are grouped by outcome (pass, fail, auto-fail, not applicable) so your team can focus human review where it’s needed.
What Auto-QA looks like in practice
In the demo, Conor built an FCA compliance scorecard and showed how it runs at scale. A few things worth knowing:
- Build the scorecard the way that suits you. You can draft it in a tool like Excel first - using comments and track changes to collaborate - then bring it into Conversation Analytics. Each criterion is defined across what to detect, what to listen for, and how to score it, using a decision tree where possible to keep scoring consistent.
- It handles vulnerability. The scorecard can detect drivers of vulnerability across health, life events, resilience and capability, and score whether the agent acknowledged, semi-acknowledged or missed the indicators - directly relevant to the FCA’s focus on vulnerable customers.
- Schedules do the running. Choose an always-on schedule (new calls scored as they come in) or a one-time run (for example, 5% of last quarter’s calls to check historical compliance). Add rules - minimum call length, successful outcomes only - set the sample size, activate, and it runs.
- Filter and report on what matters. Build views by result - passes, fails, auto-fails - and drill into any call to see the evaluation summary and exactly why it failed. Performance reporting breaks results down by campaign, team and user, with more question-level reporting arriving shortly.
Common questions from the session
Isn’t AI scoring just swapping one compliance risk for another? No - because it isn’t a black box. Every score links straight back to the exact part of the transcript it came from, so a QA lead can check any result against the call in seconds. The AI decides what needs looking at; a human still decides what to do about it.
We already run Conversation Analytics with AI Call Scoring - is Auto-QA a big project? No. It sits on infrastructure you already have, so it’s a matter of turning the feature on. Your existing scorecards carry straight over — you’re not rebuilding anything. What changes is that scoring runs on a schedule against every eligible call, rather than a person choosing which calls to score.
Can results be shown to agents, not just QA? This is in development, and it’s permissions-based - you control the level of detail. The plan is three layers of feedback: calls scored in real time as they happen, a daily “top three to improve, top three strengths” summary, and the same across a rolling seven-day view.
The takeaway
The rules have changed, and sampling no longer counts as evidence. When breaches hide in the calls you don’t review, and feedback takes three days to land, the fix is coverage that’s complete, evidenced and fast. That’s exactly the gap Auto-QA is built to close.
About MaxContact
MaxContact is an AI-powered customer engagement platform that helps businesses turn every customer conversation into a revenue-driving outcome. Our platform spans contact centre software, conversation analytics, and AI agents and chatbots - working together as one connected solution. Book a demo.
Auto QA is live: every call scored, every score evidenced
Auto QA is available today as an add-on to MaxContact Conversation Analytics.
Auto QA scores 100% of your eligible interactions against your own criteria and links every score back to the exact exchange in the transcript. When a regulator, an ombudsman or the board asks about a specific call, the evidence already exists.
Reviewing every call turns out not to be the finish line
We surveyed 300 UK contact centre managers and directors in August. 285 of them operate under FCA regulation, and among that group, 46.7% already have AI reviewing every single call. For years the case for automating Quality Assurance was that you could only ever listen to a fraction of your conversations. For half this market, that's no longer the problem. So, we asked those same 285 people whether they'd ever found a compliance breach or harm issue outside their routine Quality Assurance sample.
54.0% said yes. 16.5% had found more than one.
Reviewing everything, it turns out, isn't the same as being able to prove anything. Consumer Duty doesn't ask whether a conversation was recorded or even scanned. It asks for an assessment against defined criteria, applied consistently, with an audit trail and a demonstrable link between what you found and what you did about it. Plenty of businesses now have automated review across all their calls. Far fewer could produce that chain for one named customer, on one named call, this week.
The part that costs money is the wait
The other finding that shaped this product was about speed. Only 10.9% of regulated – businesses get feedback to an agent within a day of the call. The mean is 3.08 days. And when we asked what stops teams reviewing more, the answers were about resource rather than capability - time, cost and headcount accounted for 67.4% between them. Three days is a long time on a contact centre floor. A missed disclosure or a mishandled vulnerability marker usually isn't a one-off; it's a habit, and it carries on across conversations nobody has flagged yet.
The end of the Quality Assurance Sample
Every eligible interaction is scored automatically, as soon as the transcript is available. There are no selection step and no queue. Scorecard criteria are written in plain English rather than built from keyword rules or complex logic, so your Quality Assurance team can create and change them quickly and without waiting on us. Every score is evidence-linked, so a result can be defended in a coaching session, an internal audit or a regulatory review.
And because it's one evidence layer rather than three, Operations, Quality Assurance and Compliance are working from the same view of the same conversations instead of separate samples and separate conclusions. Your reviewers keep the final say throughout. They can challenge a score, question an output and recalibrate criteria whenever the operation changes.
If you already use MaxContact’s Conversation Analytics, you already have AI Call Scoring. That lets your team score selected calls against your existing scorecard, taking a review from roughly thirty minutes down to five - around four days a month back for a reviewer. Auto QA is the paid add-on that removes the selection step entirely and turns that output into a complete, auditable record across every call.
Available today
Auto QA is available now as an add-on to Conversation Analytics. Existing customers can speak to their Customer Success contact about switching it on. If you'd like to see it working on your own call volume rather than ours, book a demo and we'll walk you through it.
Sales want to push performance. Compliance want to protect against risk. 77.5% of the managers and directors in our research agreed that pushing performance raises compliance risk - so this isn't a tension anyone needs convincing of. Score every call and both teams are at least arguing from the same evidence.
Let sales win. Let compliance sleep.
The full research is in Confidence Is Not Evidence: The 2026 UK Conduct Risk Report - findings from all 285 regulated respondents, plus five questions we think belong in a Consumer Duty board report this year. For more on how automated Quality Assurance works in practice, see AI Quality Assurance in Contact Centres: Why Reviewing Every Call Isn't Enough.